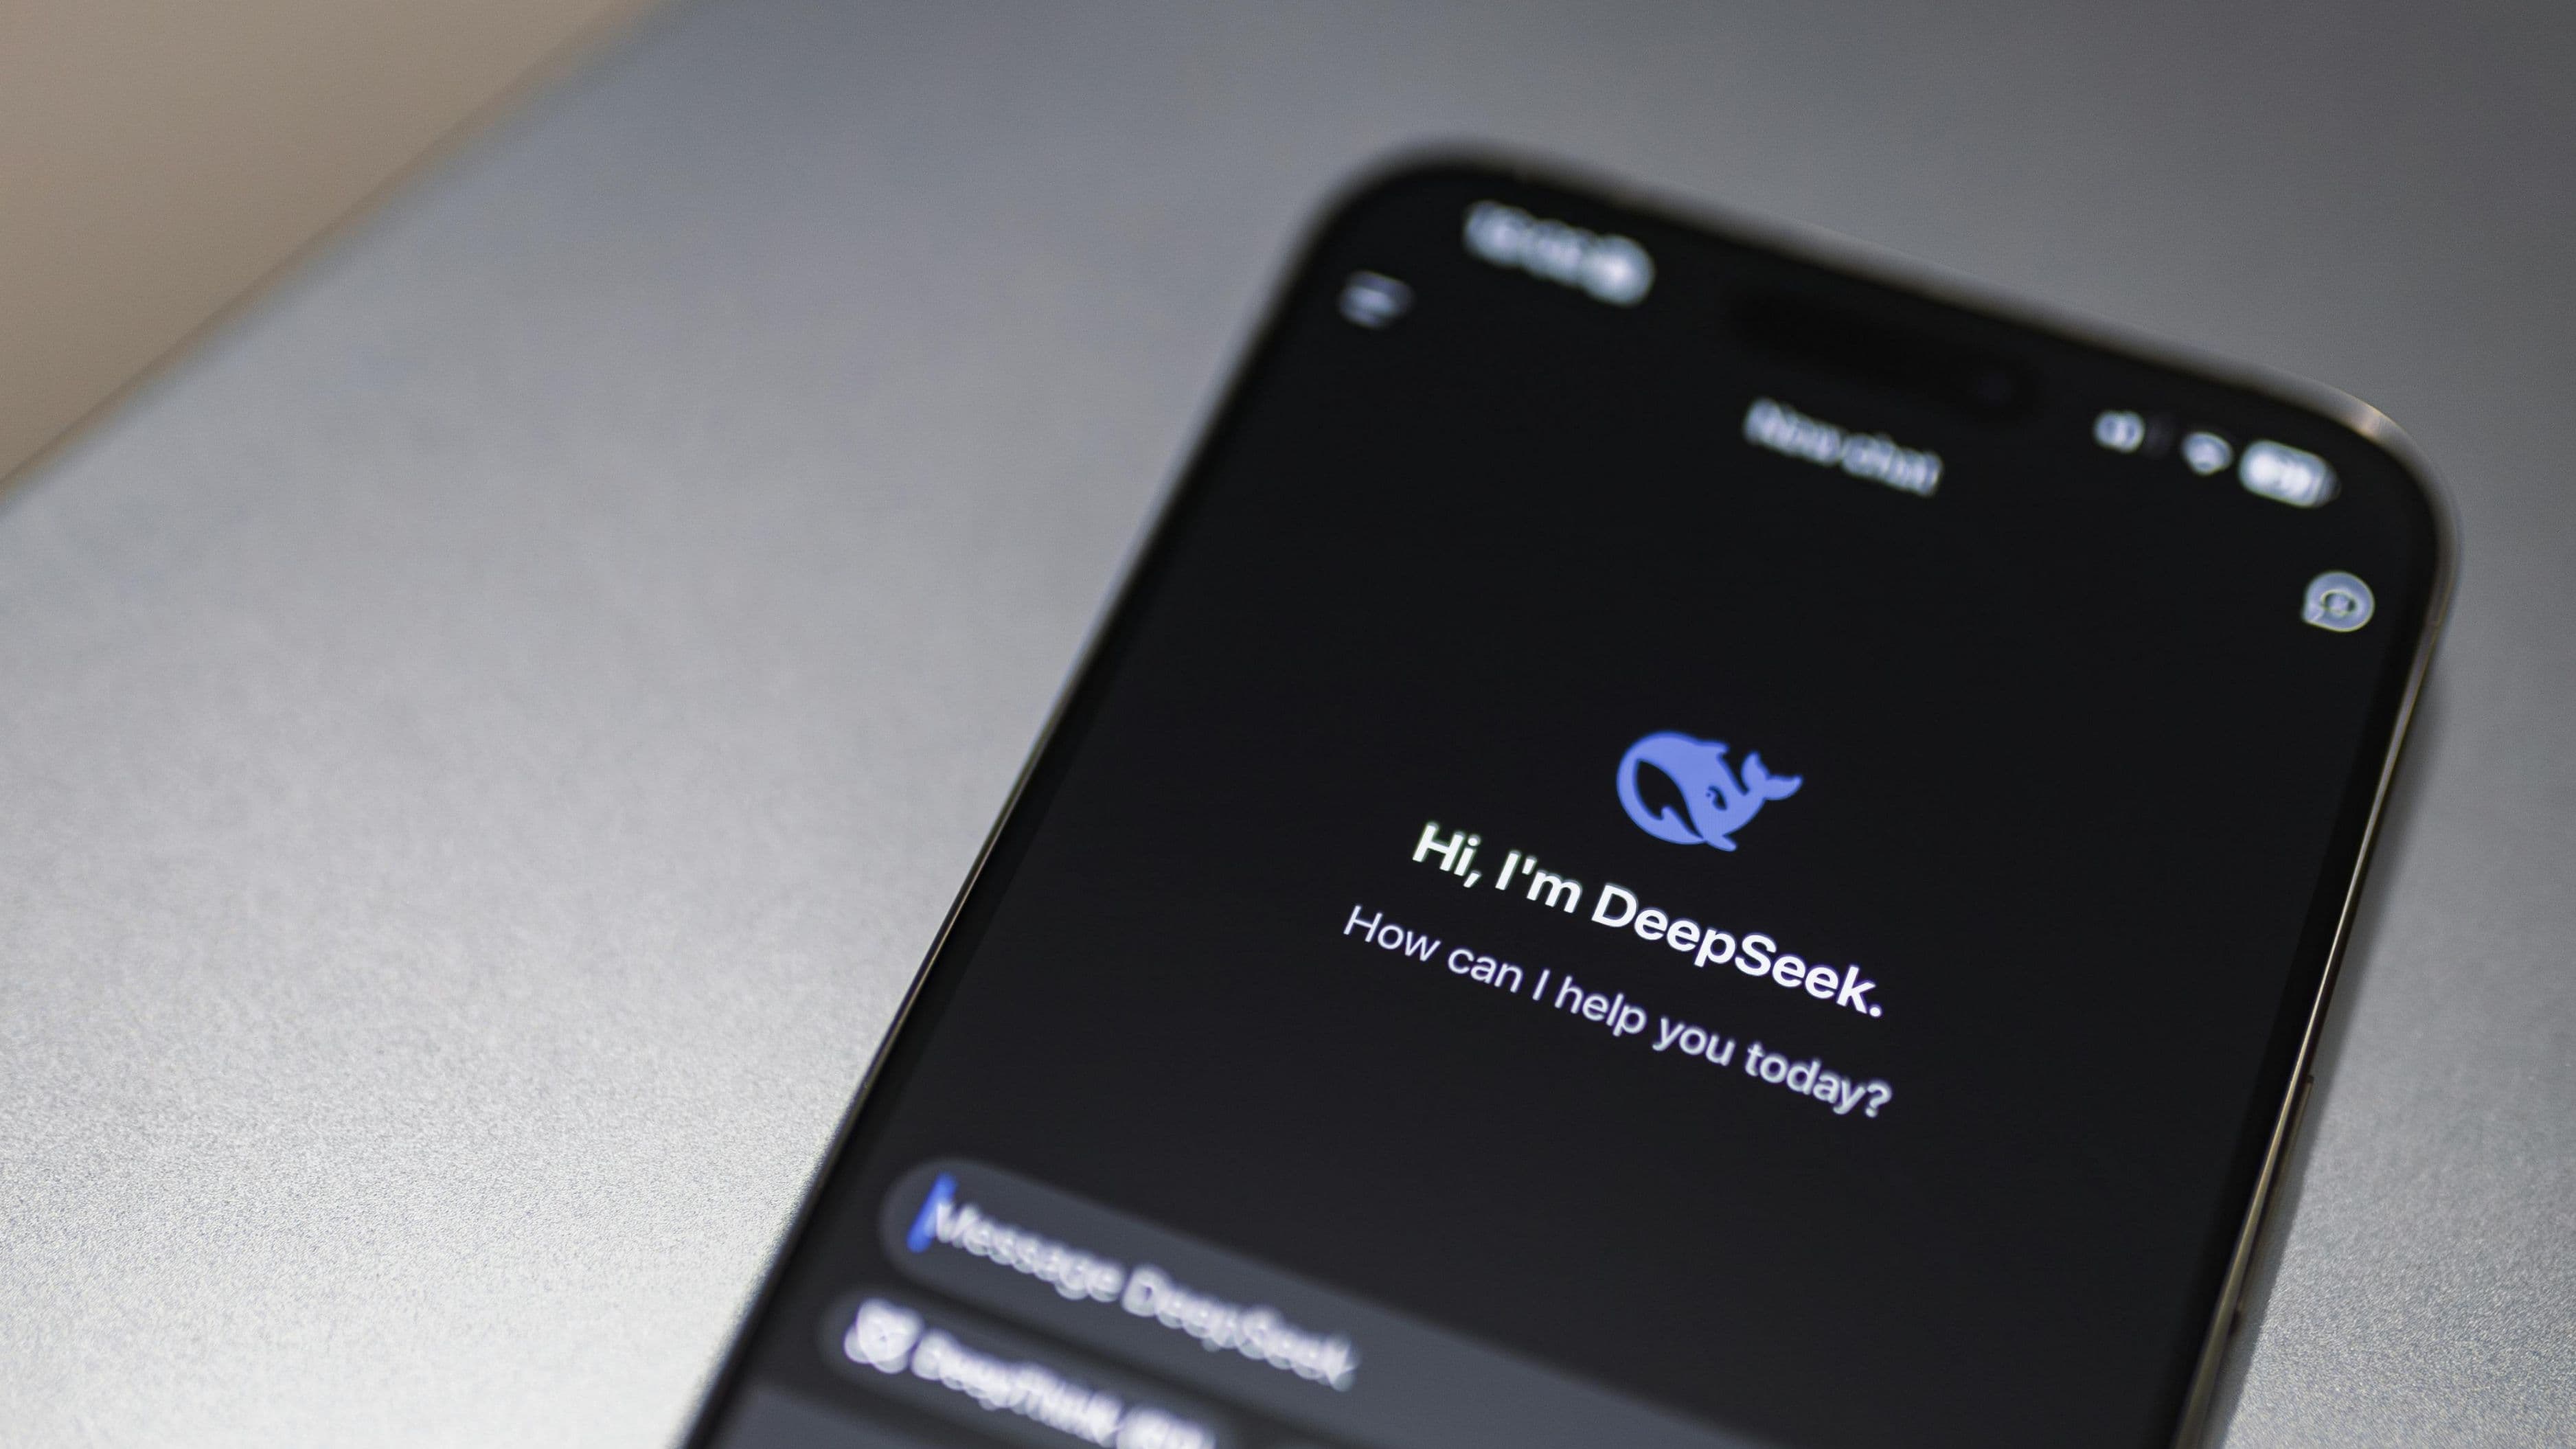
That shift matters more than a leaderboard score. It changes who gets to build with AI, who controls the data flowing through it, and how fast the whole field moves.
The Gap Is Closing Faster Than Expected
Just two years ago, open models trailed the best closed systems by a wide margin on reasoning, coding, and multi-step tasks. That gap has narrowed considerably. Open releases from labs like Meta, Mistral, and a growing list of Chinese labs now compete directly with proprietary offerings on many practical benchmarks, sometimes matching or beating them on specific tasks like code generation or long-context retrieval.
Part of this comes down to compounding know-how. Techniques that used to be closely guarded trade secrets, like better data curation, more efficient training methods, and smarter fine-tuning approaches, have diffused through research papers, conference talks, and open codebases. Once a technique is published, it tends to spread across every team paying attention, open or closed.
Why Developers Keep Choosing Open Weights
Ask a developer why they picked an open model over a closed API, and the answer usually isn't "it scored higher on a benchmark." It's control.
With an open-weight model, a team can run it entirely on their own infrastructure. That means no sending sensitive customer data to a third-party API, no dependency on someone else's uptime, and no risk of a vendor changing pricing or shutting down access overnight. For companies in regulated industries, like healthcare or finance, that control isn't a nice-to-have. It's often the difference between being allowed to use AI at all or not.
There's also the cost angle. Running an open model on your own hardware, or through a low-cost inference provider, can be dramatically cheaper at scale than paying per-token fees to a closed API, especially for high-volume, repetitive tasks like classification or summarization.
Finally, there's the ability to fine-tune. Closed models let you nudge behavior with prompts and, in some cases, limited fine-tuning APIs. Open models let you retrain the thing itself on your own data, producing a model that's genuinely specialized rather than generically capable.
Where Open Source Is Still Losing
None of this means open source has won outright. Closed frontier labs still tend to hold the lead on the hardest reasoning and agentic tasks, the kind that require chaining together dozens of steps without losing the thread. Training a truly frontier-scale model also still requires an enormous amount of compute, and that compute is expensive enough that only a small number of organizations, open or closed, can afford to do it from scratch.
Open models also inherit a harder safety problem. Once weights are released, they can be modified, stripped of safeguards, or repurposed in ways a closed API provider could never allow. That's a real tension: the same openness that lets a small startup build something useful also lets a bad actor strip out guardrails.
There's also a quieter issue: many "open" models aren't fully open in the way people assume. Some release weights but not training data. Others attach licenses that restrict commercial use above a certain scale. The open-source AI movement is winning on availability and community momentum, but it hasn't fully solved the harder questions of transparency and true openness.
The Ecosystem Effect
Perhaps the biggest reason open source is gaining ground has less to do with any single model and more to do with the ecosystem growing around it. Tools for fine-tuning, quantizing, and deploying open models have matured fast. A developer can now take an open-weight model and get it running efficiently on a single consumer GPU, something that would have required a small cluster just a couple of years ago.
That accessibility creates a flywheel. More people experimenting means more fine-tunes, more benchmarks, more bug reports, and more improvements feeding back into the base models. Closed labs move fast internally, but they don't get the benefit of thousands of independent developers stress-testing their model in public and publishing what they find.
What This Means for Everyday Users
You probably don't need to pick a side in this debate to feel its effects. Many of the AI features showing up in apps you already use, from writing assistants to customer support chatbots, are increasingly built on open-weight models under the hood, chosen because they're cheaper to run at scale and easier to customize for a specific use case.
For businesses evaluating AI tools, the practical takeaway is this: open-weight options are now legitimate contenders, not just a budget fallback. The right choice still depends on the task. A company that needs the absolute best performance on complex reasoning might still lean toward a closed frontier model. A company that needs privacy, cost control, or the ability to run offline has a much stronger open-source case today than it did even a year ago.
What to Watch Next
The next stretch of this story will likely hinge on two things: whether open models can close the remaining gap on complex, multi-step reasoning, and whether the industry settles on clearer definitions of what "open" actually means. Regulatory attention is also increasing, and how governments choose to treat open-weight releases, especially around safety disclosure, could reshape the pace of releases going forward.
For now, the trend line is clear. Open source isn't replacing closed AI, but it's no longer the underdog it was framed as a couple of years ago. It's winning on access, cost, and flexibility, even as it keeps working through the harder problems of safety and true transparency.
📚 Sources
Stanford HAI, "The 2024 AI Index Report" – https://aiindex.stanford.edu/report/
Hugging Face, "Open LLM Leaderboard" – https://huggingface.co/spaces/open-llm-leaderboard/open_llm_leaderboard
Mozilla Foundation, "Open Source AI: A Practical Guide" – https://foundation.mozilla.org/en/research/library/